
TABLE OF CONTENTS
GPU networking is the set of links, switches and protocols that let GPUs exchange data with each other, both inside a server and across a cluster. In AI training, this network matters as much as the GPUs themselves. GPUs must synchronize their results many times during every training step, so one slow or failing link can hold up the whole job.
We will walk through GPU networking from the architecture down to the physical layer: how GPUs talk inside a server, how clusters are wired together, and which cables and fiber connections carry the traffic.
Why GPU Clusters Need a Different Network
A traditional data center network moves many independent flows: web requests, database queries, file transfers. An AI training cluster behaves differently.
When a model is trained across many GPUs, each GPU computes part of the work and then shares results with the others through collective operations. NVIDIA’s NCCL library, for example, provides AllReduce, AllGather, ReduceScatter and AlltoAll. In an AllReduce, data from every GPU is combined (for example summed), and the result is delivered back to all of them. In Meta’s words, this synchronization “requires the transfer of large amounts of data among the GPUs within milliseconds, repeated over multiple iterations until the model converges.”
Two consequences follow:
- The slowest link sets the pace. A collective finishes only when every participant has finished. One congested path or a link that keeps retraining slows every GPU in the job.
- Predictable latency matters as much as raw bandwidth. A network with high average throughput but unpredictable delays still wastes GPU time.
Failures matter too. During a 54-day period of Llama 3 405B pre-training, Meta recorded 466 job interruptions. Of these, 47 were planned and 419 were unexpected. “Network Switch/Cable” accounted for 35 of the unexpected interruptions (8.4%), and NICs for another 7 (1.7%). Faulty GPUs and GPU memory were larger causes, and the team still achieved more than 90% effective training time. We are not saying networks are the main problem. We are saying that at this scale, cables and switches fail often enough that you have to plan for it.
Scale-Up vs. Scale-Out
GPU networking has two layers that are often confused.
| Scale-up | Scale-out | |
|---|---|---|
| Scope | GPUs inside a server or rack-scale domain | GPUs in different servers and racks |
| Typical technology | NVLink and NVSwitch | InfiniBand or Ethernet (RoCE) |
| Bandwidth example | 900 GB/s per GPU (NVLink, Hopper); 1,800 GB/s (Blackwell) | Up to 400 Gb/s per NIC (ConnectX-7); 800 Gb/s (ConnectX-8) |
| Physical media | Board traces, NVLink cables and backplanes | Copper cables, active cables, optical transceivers and fiber |
Take care with the units: NVLink figures are in gigabytes per second, while network ports are rated in gigabits per second. The two layers do different jobs and don’t compete. Scale-up links the GPUs of one node or rack tightly. Scale-out lets thousands of those nodes work as one cluster.

The Four Networks Inside an AI Data Center
An AI cluster usually runs several separate networks. NVIDIA’s DGX SuperPOD reference architecture for H100 systems defines four:
- Compute (back-end) fabric. This carries GPU-to-GPU traffic between nodes. Each DGX H100 system has eight ConnectX-7 adapters for this network, at up to 400 Gb/s each, exposed through four OSFP ports. That works out to one network adapter per GPU. Meta’s Grand Teton training servers follow the same 1:1 mapping between GPUs and NICs.
- Storage fabric. This feeds training data and saves checkpoints. The SuperPOD design states that I/O per node “must exceed 40 GBps.”
- In-band management. This connects the services that run the cluster, such as job scheduling, code repositories and data sources. In DGX H100, storage and in-band traffic use two dual-port ConnectX-7 cards.
- Out-of-band management. This reaches each server’s BMC for power, monitoring and recovery. On DGX H100 it is a 1 GbE RJ45 port, kept separate from the other networks.
Keeping these networks apart isolates faults and keeps training traffic predictable. For cabling, it means each GPU server may need eight or more high-speed optical links for compute alone, plus separate storage and management connections.
Back-End Fabric Design: Topology, Rails and Lossless Transport
Leaf-spine and rail-optimized design
Most GPU back-end fabrics use a leaf-spine (Clos) topology. GPU clusters add a refinement called rail optimization, or rail alignment. In an eight-GPU server, GPU 1 connects to one leaf switch, GPU 2 to another, and so on. The set of all “GPU 1” ports across a group of servers forms a rail.
In the DGX H100 SuperPOD, each scalable unit (SU) of 32 nodes is rail-aligned. As NVIDIA puts it, traffic on a rail “is always one hop away from the other 31 nodes in a SU,” while traffic between rails or SUs “traverses the spine layer.” The full reference design connects 127 nodes. Rail alignment keeps most collective traffic on short, predictable paths. It works best when the job scheduler is aware of the topology.
InfiniBand vs. RoCE
The scale-out fabric typically runs one of two RDMA transports:
- InfiniBand is purpose-built for high-performance computing. It has built-in congestion control and adaptive routing, and it has long been the default in NVIDIA reference designs.
- RoCE (RDMA over Converged Ethernet) runs RDMA on Ethernet switches. Meta runs RoCE at large scale. It has shared designs for clusters of up to 32,000 GPUs, and a large Llama 3 variant was trained on 16,000 GPUs on a 24,000-GPU RoCE cluster.
RoCE needs careful tuning. Meta reported using DSCP-based priority flow control (PFC) with a single lossless queue. It first tried DCQCN congestion control, then moved congestion management into the collective library itself. “Lossless” in this context is a design goal that depends on end-to-end configuration, not a guarantee that packets never drop.
Ethernet for AI is still developing. The Ultra Ethernet Consortium released its UEC Specification 1.0 on June 11, 2025, covering the stack from NICs and switches to optics and cables. It is a new specification, not yet a replacement for either option above.
From Fabric to Physical Links: Cables, Optics and Connectors
This is where the architecture diagram meets the cable tray, and where we see many AI builds run into trouble.
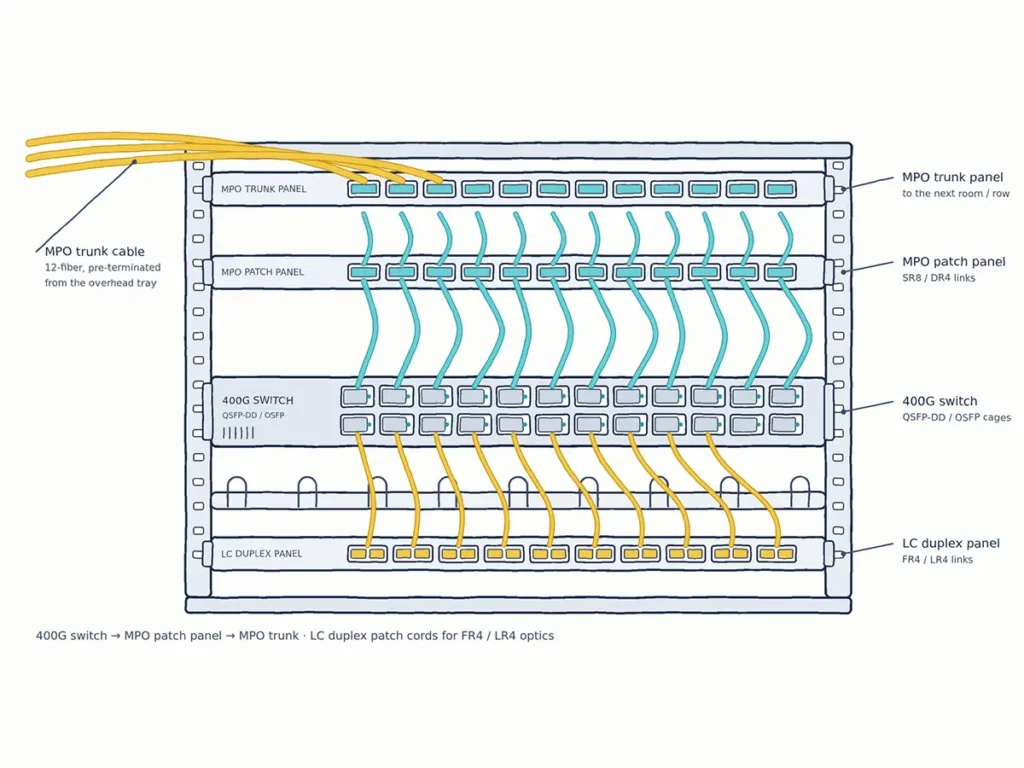
Link types. GPU clusters mix several media. Passive copper (DAC) and active copper (ACC or AEC) cables serve very short runs inside a rack or to an adjacent rack. Active optical cables (AOC) cover longer fixed runs. For links between rows and rooms, and for any link you want to re-patch later, clusters use pluggable optical transceivers with structured fiber cabling. Reach limits depend on the exact product, so check each vendor’s specification rather than assuming a rule of thumb.
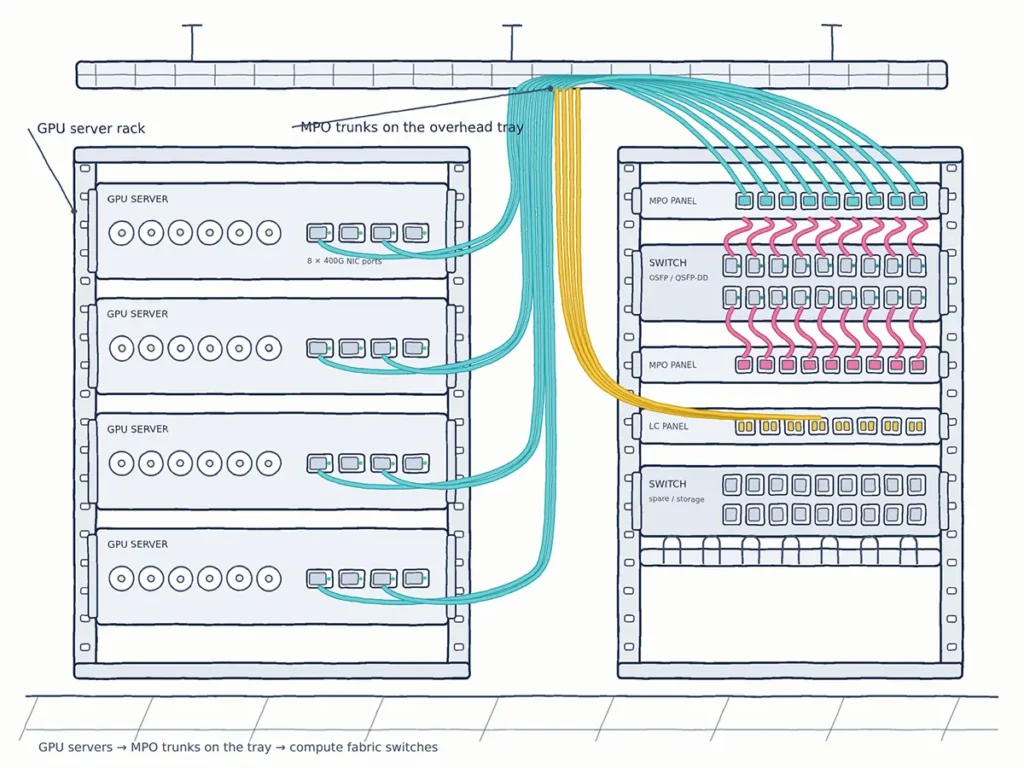
Let us make that concrete. On NVIDIA’s air-cooled 400G InfiniBand and Ethernet switches, each OSFP cage holds two 400 Gb/s ports. The matching 800G twin-port transceiver contains two DR4 engines and has two MPO-12/APC single-mode connectors, one per 400G port, each using eight fibers (four transmit, four receive). NVIDIA gives a maximum reach of 500 m and notes that its 100 m cable length “assumes two optical patch panels in the link.” On the server side, each 400G ConnectX-7 port takes a matching DR4 optic. The result is a large number of MPO-12/APC single-mode links. For how DR4 and other 400G optics map to fiber, see our 400G network guide.

Scale is the real challenge. Multiply eight compute links per server by hundreds of servers, add spine uplinks, storage and management, and the fiber count rises quickly. There is no reliable industry figure for “fiber per GPU,” because it depends on topology. Count it from your design: nodes × ports per node × fibers per port, plus trunks, patch panels and spares. The practical problems are density, cable routing, labeling, and keeping thousands of MPO end faces clean.
This is where cabling quality becomes cluster performance. Low-loss MPO/MTP cords leave room in the loss budget for patch panels. Consistent polarity and correct pinning prevent links that simply stay dark. Clean, inspected connectors cut down on the link errors and flaps that slow collectives.
Common GPU Network Problems and How to Catch Them Early
Here are the issues we see most often, working from the physical layer up:
- Links that flap or show rising error counters. Start at the physical layer. Inspect and clean both end faces, reseat the optic, and check the fiber path and polarity. Don’t clear the counters until you have recorded them. Rising FEC-corrected errors do not always mean a dirty connector, but it is the cheapest cause to rule out.
- Some lanes or ports stay down. Check port mode and breakout configuration, pinned/unpinned mating, polarity method, and APC/UPC mismatch.
- Throughput lower than expected with no obvious fault. Look at traffic balance across rails and spine links, congestion settings and job placement. Engineers on forums report training runs losing throughput with no errors on the ML side. Treat these as anecdotes rather than statistics, but they show that the network is worth checking first.
- Problems inside the server. AMD’s cluster troubleshooting guide advises checking “PCIe link status on all the devices in the CPU-to-NIC packet datapath.” A degraded PCIe link can look exactly like a network problem.
- Hard-to-reproduce hangs. Collective-level tracing helps. Meta’s Llama 3 team used NCCL flight recording to capture collective metadata and timing when jobs stalled.
Before go-live, test insertion loss on every link, verify polarity, label both ends of every cord, and record baseline error counters. Future troubleshooting will depend on that baseline.
Passive Connectivity for GPU Clusters from YingFeng
AI clusters stand or fall on thousands of small, repetitive connections. YingFeng has 25+ years of fiber optic manufacturing experience and makes the passive parts of those links:
- MPO/MTP patch cords and trunks in 8-, 12-, 16- and 24-fiber counts, including low-loss versions, produced in a cleanroom.
- LC and other duplex patch cords for storage, management and FR4-type links.
- Connector kits and components for assemblers building their own AI cabling, with custom tooling available.
Share your cluster size and transceiver list, and we will help you build a matching patch cord BOM. OEM/ODM service is available and samples are provided on request. See also our data center fiber optics solutions.
FAQ
What is GPU networking?
GPU networking is the interconnect that lets GPUs exchange data, both inside a server (NVLink/NVSwitch) and between servers (InfiniBand or Ethernet/RoCE). In AI training it carries the collective operations that keep all GPUs synchronized.
What is the difference between scale-up and scale-out?
Scale-up connects GPUs within a server or rack-scale domain with very high bandwidth, such as 900 GB/s per GPU with Hopper NVLink. Scale-out connects many servers over a network fabric, typically at 400–800 Gb/s per network adapter.
Is InfiniBand or Ethernet better for GPU clusters?
Both are used at large scale. InfiniBand offers mature built-in congestion control. RoCE on Ethernet has been proven at large scale by operators such as Meta but needs careful tuning. The right choice depends on scale, existing skills and supplier strategy.
What is a rail-optimized network?
In a rail-optimized network, the same-numbered GPU in each server connects to the same leaf switch. In NVIDIA’s DGX H100 SuperPOD, this keeps traffic within a 32-node unit one hop away on each rail.
What cables connect GPU servers to switches?
It depends on distance. Copper DAC or active copper cables serve very short in-rack runs. For longer links, clusters use optical transceivers, often 400G DR4 with MPO-12/APC single-mode patch cords, or active optical cables.
External references
- NVIDIA DGX SuperPOD H100 reference architecture, network fabrics: https://docs.nvidia.com/dgx-superpod/reference-architecture-scalable-infrastructure-h100/latest/network-fabrics.html
- NVIDIA NCCL collective operations: https://docs.nvidia.com/deeplearning/nccl/user-guide/docs/usage/collectives.html
- Meta, “RDMA over Ethernet for Distributed AI Training at Meta Scale” (SIGCOMM 2024)
- “The Llama 3 Herd of Models,” arXiv:2407.21783
- Ultra Ethernet Consortium, Specification 1.0 announcement (June 11, 2025)